 Do Son
Tech giants support a new AI training preference standard in robots.txt, giving publishers granular control over model training data.
Web Scraping
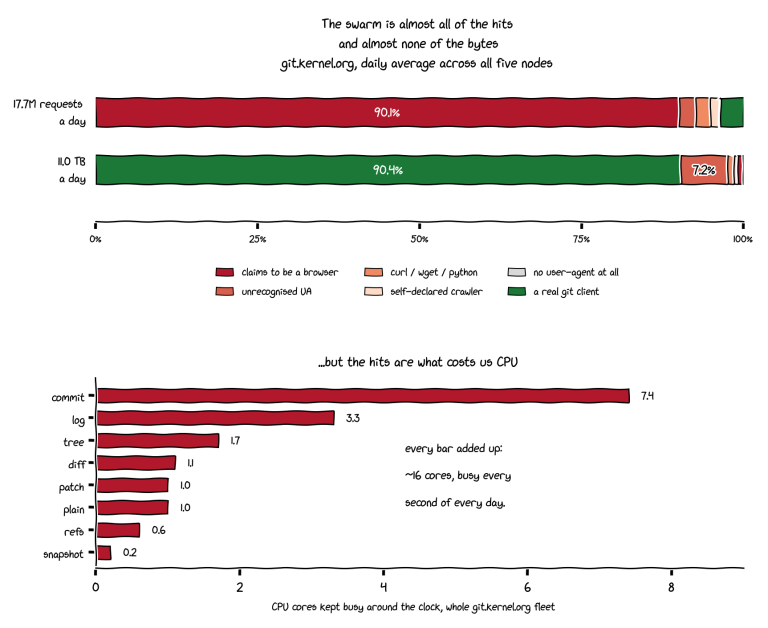
AI crawlers now burden git.kernel.org with 6M daily requests, burning more CPU rendering commits for scrapers than on all legitimate access combined.

Cloudflare CEO Matthew Prince warns that AI bot traffic will soon eclipse human users. Discover the data behind the 2026 internet traffic paradigm shift.
Cloudflare accuses Perplexity AI of ignoring robots.txt files and impersonating a browser to evade detection, and has removed it from its list of verified bots.

The Free Software Foundation reports ongoing DDoS attacks since Aug 2024, with much traffic from AI company crawlers. Its small team is overwhelmed by the relentless web scraping.
Cloudflare launches "Pay Per Crawl," allowing websites to charge AI companies for content scraping. Publishers can set prices, aiming for a new economic model for the web.

Cloudflare launched an AI Crawler Leaderboard ranking AI company web crawlers. ByteDance is last for ignoring robots.txt and lack of IP transparency, prompting new blocking defaults.

Facing overwhelming AI web scraping, Wikimedia releases a free, optimized dataset on Kaggle to encourage direct downloads and reduce server strain.

Learn about AkiraBot, an AI-powered spam bot that uses OpenAI to generate personalized messages and flood website contact forms and chat widgets, as detailed in a SentinelLABS report.

HTTP headers are widely used during web scraping because they allow access to otherwise blocked information. Competitor...