 Do Son
Anthropic officially unveiled its next-generation foundation models, Claude Fable 5.2 and Claude Mythos 5.2. Specifically, the updated architecture significantly elevates code generation, mathematical reasoning, and visual perception. In addition, standard API pricing dropped by twenty percent compared to preceding models. Consequently, developers gain access to flagship intelligence at eight dollars per million input tokens. Furthermore, early evaluations position the model at the summit of global capability rankings.
Top Benchmark Scores and Coding Performance
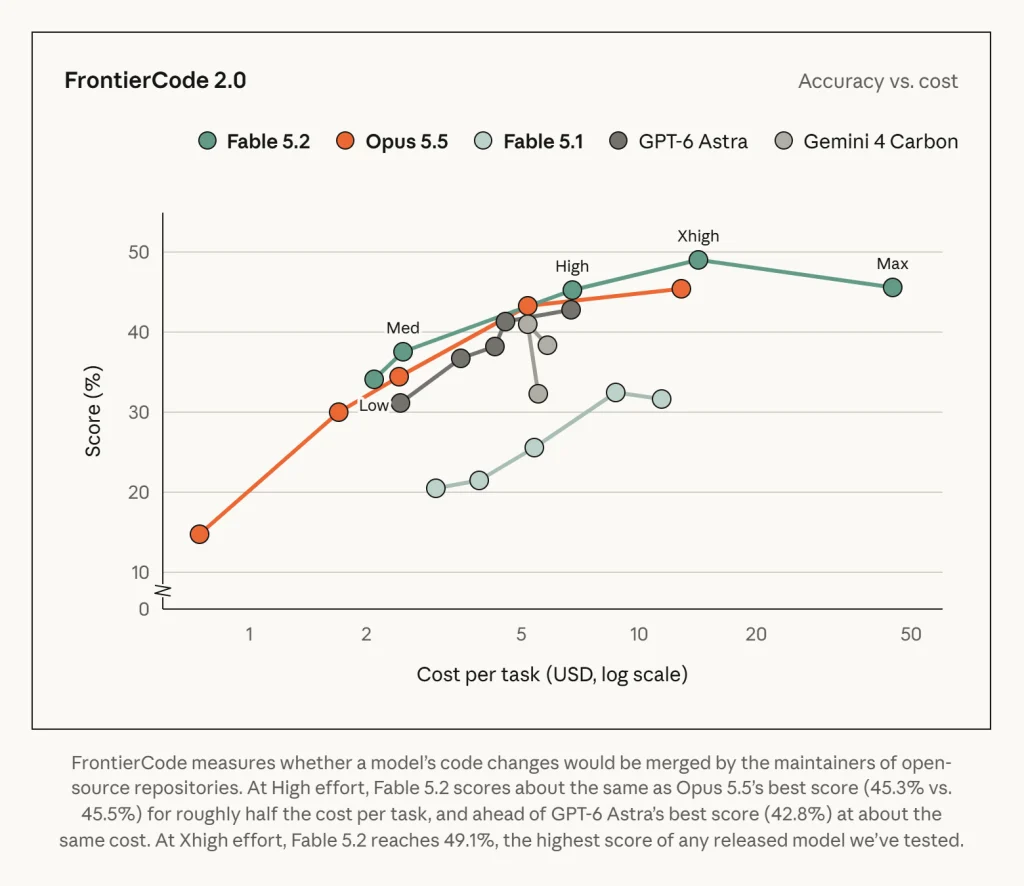
Independent evaluations confirm substantial leaps across rigorous programming benchmarks. On the FrontierCode 2.0 evaluation, Claude Fable 5.2 attained a stellar 49.1 percent accuracy rating. For comparison, earlier iterations like Claude Fable 5.1 achieved only 32.4 percent. Similarly, the system reached 69.9 percent on the demanding FrontierSWE V2 software engineering test.
According to the official Anthropic release announcement for Claude Fable 5.2, processing efficiency improved markedly. Moderate reasoning intensities require fewer tokens while boosting throughput speed by thirty percent. However, peak reasoning configurations demand considerable processing time and financial investment. Comprehensive tests recorded an average expenditure of 26.54 dollars per completed benchmark assignment.
API Pricing Structure and Fast Mode Deployment
The flagship model accommodates an expansive context window of one million tokens. Simultaneously, maximum output limits reach 128,000 tokens for comprehensive document generation. Standard pricing remains fixed at eight dollars per million input tokens and forty dollars per million output tokens. Prompt caching reads cost a negligible twenty cents per million tokens.
Optimizing Workflows Across the Claude Family
Additionally, Anthropic introduced an optional accelerated processing tier termed Fast Mode. This specialized setting amplifies execution speed up to 2.5 times standard throughput rates. However, accelerated execution doubles expenditure to sixteen dollars per million inputs and eighty dollars per million outputs.
Therefore, Anthropic recommends deploying Claude Opus 5.5 for routine software maintenance and analytical research. Engineers should reserve Claude Fable 5.2 for intricate problem sets requiring extensive architectural reasoning. Ultimately, flexible reasoning controls allow software teams to balance cost, latency, and predictive performance effectively.
Support Our Threat Intelligence
Find our tech and OS security coverage helpful? Support our work today and unlock a 100% ad-free reading experience!
 Buy Me a Coffee
